Traditional written assessments were designed for a different era. They assume candidates can read fluently, navigate complex digital interfaces, and process instructions in a language that may not be their first. For HR teams hiring warehouse operatives, logistics staff, care workers, or production line roles, that assumption quietly disqualifies capable people and leaves genuine talent undetected.
This guide is for HR managers, recruiters, and talent acquisition leads running high-volume or multilingual hiring programmes. By the end, you'll have a pilot-ready blueprint for building accessible, inclusive assessment methods that work on a smartphone, accommodate language barriers, and measure actual job skills rather than literacy or digital confidence.
Expected difficulty: moderate. Expected time to pilot: 2 to 10 weeks depending on scope.
Before getting into the "how", it's worth being clear about what's actually at stake.
When a candidate fails a written screening test, you need to ask: did they fail because they lack the job skill, or because the assessment required a level of English literacy that the role itself does not? If it's the latter, you've not screened for competence; you've screened for language. That's not just an inclusion concern. It's a construct validity problem.
Ofqual's guidance on designing and developing accessible assessments (GOV.UK) sets out the regulatory principle clearly: an accessible assessment should measure what it claims to measure, not an unintended barrier. The OECD's working paper "How can adult skills assessments best meet the demands of the 21st century?" makes a similar point at policy level, calling for flexible testing in real-world contexts. Neither source tells you how to build it. That's what this guide does.
This matters most when you're hiring for practical or operational roles, sourcing from multilingual communities or migrant worker populations, or running high-volume campaigns where drop-off rates directly affect your pipeline.
Start here, before you design a single question.
Write down the job skill target for each assessment component. Be specific. Not "communication", but "can understand a verbal safety instruction and confirm receipt". Not "problem-solving", but "can prioritise two competing tasks when given a scenario".
Use this table to map each skill to a format that doesn't require strong literacy or advanced digital navigation:
Once you have your skill-format map, you have a defensible assessment design. Every subsequent decision should serve it.
For candidates with limited written English or low digital literacy, these formats consistently outperform standard text-heavy tests:
Structure every task into no more than three steps at a time. Confirm completion with a visible checkpoint before moving forward. Show a brief example item before the scored section begins so candidates understand the format.
Good intentions fall apart at the design stage. These patterns prevent the most common failure modes.
Write audio scripts in short sentences at a reading age of around 9 to 11. Read the script aloud yourself before recording; if you stumble, rewrite. Provide a repeat button on every audio prompt. Ensure the recording is consistent in tone, pace, and volume across all items.
Use a consistent icon set throughout. Don't swap icon styles between sections. Every icon should support task comprehension; remove any that are decorative. Keep each screen to a single task. Predictable navigation (back, next, replay) should always appear in the same position.
Replace multi-sentence instructions with a single action line: "Listen, then choose." Highlight the next action visually (colour contrast, size). Limit each screen to a maximum of two or three answer choices. Long scrolling pages with multiple questions visible simultaneously are one of the most common reasons candidates drop out in low-literacy populations.
Do not impose a time limit unless the job itself requires speed as an explicit, measured competency. Allow candidates to pause and resume. If a session times out, let them restart from where they left off. Speed pressure introduced by the assessment rather than the job construct produces inaccurate results and higher drop-off.
Multilingual support is not just adding a language toggle. Done poorly, it can introduce more confusion than it resolves.
Present the language choice on the very first screen, before any assessment content. Make the options visually distinct (flags plus language names written in the language itself). Confirm the selected language at the start of each new section.
Translation is the minimum. Localisation means adapting tone, removing culturally specific references, and checking that idioms don't survive into the translated version. Keep sentence structures short and parallel across all language versions so the cognitive load stays consistent.
If a candidate reaches a point where they can't continue in any available language, the system should offer an assisted intake option: a call-back, a short voice-note response, or a live conversation with a recruiter. Don't let an unresolvable language gap become a silent drop-off.
Consent language must be in plain terms and in the candidate's chosen language. Explain specifically what data is collected, how long it's kept, and who sees it. Selection Lab's platform handles this in its intake flow with explicit GDPR-aligned consent, personal data stored in Frankfurt, retention periods defined per client configuration, and local LLMs used to remove personal information from conversation logs before processing.
For roles that require workplace communication, calibrate the language difficulty to what the role actually demands. A warehouse role requiring the ability to follow a two-step verbal instruction is not the same construct as a customer service role requiring written complaint resolution. Define the language level required for the job first; design to that standard, not to academic English proficiency.
Don't scale an untested design. A small, structured pilot protects both candidates and your pipeline.
You're checking three things:
Include candidates who represent your actual hiring pool. If you're hiring multilingual migrant workers for logistics roles, your pilot cohort should include people from those communities, using those devices. Recruit across language groups and device types (Android vs iOS, older vs newer handsets, high-bandwidth vs limited-data connections).
Aim for a minimum of 20 to 30 participants per subgroup to identify meaningful patterns, though even a small pilot of 10 to 15 mixed participants will surface obvious navigation blockers.
Track: completion rate, time-on-task per section, drop-off point (which screen do people leave?), number of help requests or replays, and whether any error states were triggered repeatedly.
After the pilot, segment results by language group and device type. Look for differential drop-off: are candidates dropping at the language selection screen? At a specific question type? At the consent step? Each drop-off point has a specific fix. A drop-off at language selection means your language options aren't prominent enough. A drop-off at a specific question type often means the audio instruction isn't clear or the icon choice is ambiguous.
Until you have enough data to validate scoring at scale, set your pass thresholds conservatively. Document every change you make to wording or pacing in a change log, and note whether the change affected scoring distributions. This creates an audit trail that supports fairness sign-off before you scale.
Work through this checklist before launch.
Working through this guide gives you a defensible, pilot-ready accessible assessment process. You've defined constructs that measure job skills rather than literacy. You've applied audio, icon, and minimal-text design patterns. You've built in language support that goes beyond translation. And you've established the pilot and fairness framework needed to scale responsibly.
The evidence supports the investment. Selection Lab's data from clients using its WhatsApp-based SmartChat intake flow shows 27% fewer drop-offs, 15 minutes saved per applicant, and 21% lower early turnover compared to traditional intake methods. That's not just a more inclusive process; it's a more efficient one.
The next step is to keep accessibility as a standing part of your release process, not a one-off project. Every time you add a new role-based assessment bundle or revise question content, run the audit against this checklist. Candidate populations change, languages expand, and devices evolve. The organisations that build that review cycle in from the start are the ones that maintain both fairness and funnel performance over time.


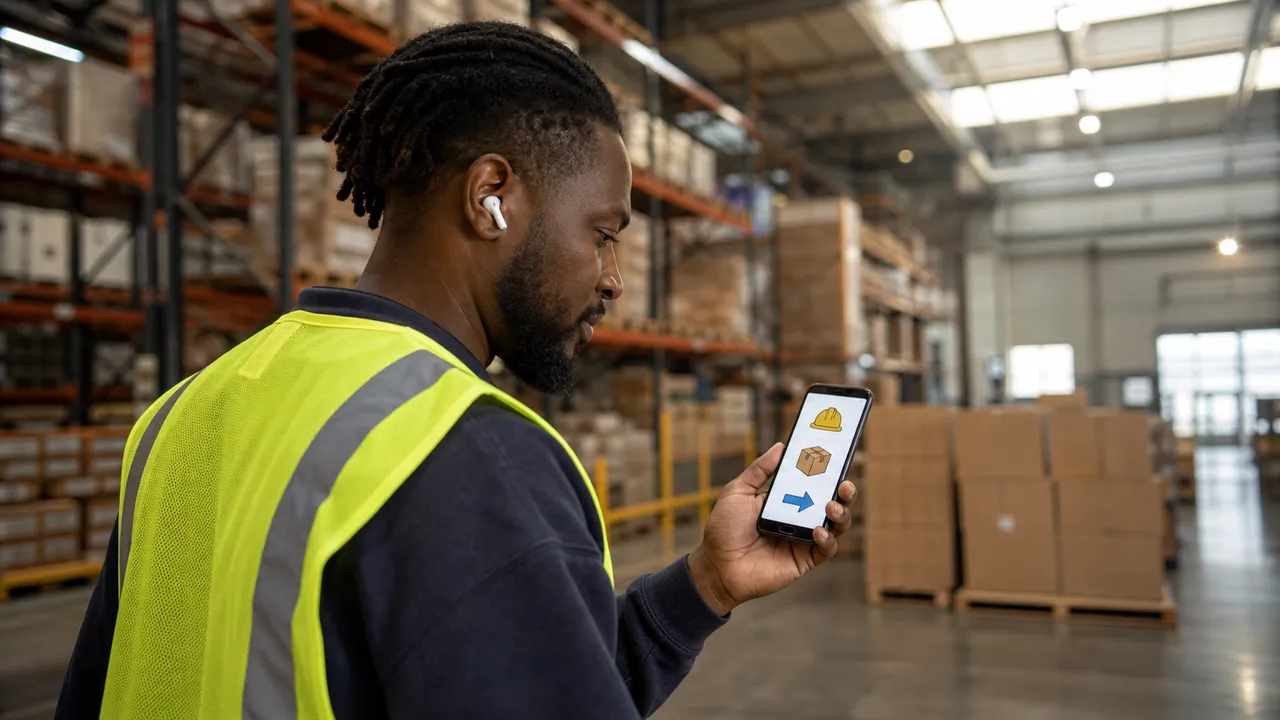
Traditional written assessments were designed for a different era. They assume candidates can read fluently, navigate complex digital interfaces, and process instructions in a language that may not be their first. For HR teams hiring warehouse operatives, logistics staff, care workers, or production line roles, that assumption quietly disqualifies capable people and leaves genuine talent undetected.
This guide is for HR managers, recruiters, and talent acquisition leads running high-volume or multilingual hiring programmes. By the end, you'll have a pilot-ready blueprint for building accessible, inclusive assessment methods that work on a smartphone, accommodate language barriers, and measure actual job skills rather than literacy or digital confidence.
Expected difficulty: moderate. Expected time to pilot: 2 to 10 weeks depending on scope.
Before getting into the "how", it's worth being clear about what's actually at stake.
When a candidate fails a written screening test, you need to ask: did they fail because they lack the job skill, or because the assessment required a level of English literacy that the role itself does not? If it's the latter, you've not screened for competence; you've screened for language. That's not just an inclusion concern. It's a construct validity problem.
Ofqual's guidance on designing and developing accessible assessments (GOV.UK) sets out the regulatory principle clearly: an accessible assessment should measure what it claims to measure, not an unintended barrier. The OECD's working paper "How can adult skills assessments best meet the demands of the 21st century?" makes a similar point at policy level, calling for flexible testing in real-world contexts. Neither source tells you how to build it. That's what this guide does.
This matters most when you're hiring for practical or operational roles, sourcing from multilingual communities or migrant worker populations, or running high-volume campaigns where drop-off rates directly affect your pipeline.
Start here, before you design a single question.
Write down the job skill target for each assessment component. Be specific. Not "communication", but "can understand a verbal safety instruction and confirm receipt". Not "problem-solving", but "can prioritise two competing tasks when given a scenario".
Use this table to map each skill to a format that doesn't require strong literacy or advanced digital navigation:
Once you have your skill-format map, you have a defensible assessment design. Every subsequent decision should serve it.
For candidates with limited written English or low digital literacy, these formats consistently outperform standard text-heavy tests:
Structure every task into no more than three steps at a time. Confirm completion with a visible checkpoint before moving forward. Show a brief example item before the scored section begins so candidates understand the format.
Good intentions fall apart at the design stage. These patterns prevent the most common failure modes.
Write audio scripts in short sentences at a reading age of around 9 to 11. Read the script aloud yourself before recording; if you stumble, rewrite. Provide a repeat button on every audio prompt. Ensure the recording is consistent in tone, pace, and volume across all items.
Use a consistent icon set throughout. Don't swap icon styles between sections. Every icon should support task comprehension; remove any that are decorative. Keep each screen to a single task. Predictable navigation (back, next, replay) should always appear in the same position.
Replace multi-sentence instructions with a single action line: "Listen, then choose." Highlight the next action visually (colour contrast, size). Limit each screen to a maximum of two or three answer choices. Long scrolling pages with multiple questions visible simultaneously are one of the most common reasons candidates drop out in low-literacy populations.
Do not impose a time limit unless the job itself requires speed as an explicit, measured competency. Allow candidates to pause and resume. If a session times out, let them restart from where they left off. Speed pressure introduced by the assessment rather than the job construct produces inaccurate results and higher drop-off.
Multilingual support is not just adding a language toggle. Done poorly, it can introduce more confusion than it resolves.
Present the language choice on the very first screen, before any assessment content. Make the options visually distinct (flags plus language names written in the language itself). Confirm the selected language at the start of each new section.
Translation is the minimum. Localisation means adapting tone, removing culturally specific references, and checking that idioms don't survive into the translated version. Keep sentence structures short and parallel across all language versions so the cognitive load stays consistent.
If a candidate reaches a point where they can't continue in any available language, the system should offer an assisted intake option: a call-back, a short voice-note response, or a live conversation with a recruiter. Don't let an unresolvable language gap become a silent drop-off.
Consent language must be in plain terms and in the candidate's chosen language. Explain specifically what data is collected, how long it's kept, and who sees it. Selection Lab's platform handles this in its intake flow with explicit GDPR-aligned consent, personal data stored in Frankfurt, retention periods defined per client configuration, and local LLMs used to remove personal information from conversation logs before processing.
For roles that require workplace communication, calibrate the language difficulty to what the role actually demands. A warehouse role requiring the ability to follow a two-step verbal instruction is not the same construct as a customer service role requiring written complaint resolution. Define the language level required for the job first; design to that standard, not to academic English proficiency.
Don't scale an untested design. A small, structured pilot protects both candidates and your pipeline.
You're checking three things:
Include candidates who represent your actual hiring pool. If you're hiring multilingual migrant workers for logistics roles, your pilot cohort should include people from those communities, using those devices. Recruit across language groups and device types (Android vs iOS, older vs newer handsets, high-bandwidth vs limited-data connections).
Aim for a minimum of 20 to 30 participants per subgroup to identify meaningful patterns, though even a small pilot of 10 to 15 mixed participants will surface obvious navigation blockers.
Track: completion rate, time-on-task per section, drop-off point (which screen do people leave?), number of help requests or replays, and whether any error states were triggered repeatedly.
After the pilot, segment results by language group and device type. Look for differential drop-off: are candidates dropping at the language selection screen? At a specific question type? At the consent step? Each drop-off point has a specific fix. A drop-off at language selection means your language options aren't prominent enough. A drop-off at a specific question type often means the audio instruction isn't clear or the icon choice is ambiguous.
Until you have enough data to validate scoring at scale, set your pass thresholds conservatively. Document every change you make to wording or pacing in a change log, and note whether the change affected scoring distributions. This creates an audit trail that supports fairness sign-off before you scale.
Work through this checklist before launch.
Working through this guide gives you a defensible, pilot-ready accessible assessment process. You've defined constructs that measure job skills rather than literacy. You've applied audio, icon, and minimal-text design patterns. You've built in language support that goes beyond translation. And you've established the pilot and fairness framework needed to scale responsibly.
The evidence supports the investment. Selection Lab's data from clients using its WhatsApp-based SmartChat intake flow shows 27% fewer drop-offs, 15 minutes saved per applicant, and 21% lower early turnover compared to traditional intake methods. That's not just a more inclusive process; it's a more efficient one.
The next step is to keep accessibility as a standing part of your release process, not a one-off project. Every time you add a new role-based assessment bundle or revise question content, run the audit against this checklist. Candidate populations change, languages expand, and devices evolve. The organisations that build that review cycle in from the start are the ones that maintain both fairness and funnel performance over time.